CUTEADMOA is a self-hosted AI platform built around CuttyMOA-1.3 — a 27-billion-parameter model with a 262,144-token context window, trained end-to-end on 204 verified datasets plus thousands of live agent sessions.
No signup. Rate-limited public demo served straight from the lab's own hardware. Full-speed API keys are available for the OpenAI-compatible endpoint.
Everything below runs on the same self-hosted stack, orchestrated around the CuttyMOA model family.
23+ engines behind one smart router, with cross-validated multi-engine answers for higher reliability.
Smart RouterSelf-trained models across four generations — 1.0, 1.2 MoE, the 1.3 flagship, and a compact 1.3-Small.
Self-trainedGeneration, review and debugging across languages — code is the single largest slice of the training corpus.
Largest corpus slice17 cybersecurity intents with severity classification, feeding HTML and DOCX report generation.
17 intentsSelenium Chrome automation, 8 pre-built extractors, AI-powered extraction, JSON/CSV export and cron scheduling.
Enterprise scrapingEntire codebases, contracts and books inside a single prompt window — natively 262,144 tokens.
Long contextTrained on function-calling corpora including BFCL, xLAM, Glaive and Hermes tool-use sets.
Function callingSpeech-to-text and text-to-speech across three engines, wired into native app voice flows.
3 enginesSix macOS control applications plus an iOS/iPad companion for full desktop and mobile integration.
6 apps + iOSA transparent, reproducible pipeline — every stage runs on infrastructure this lab controls.
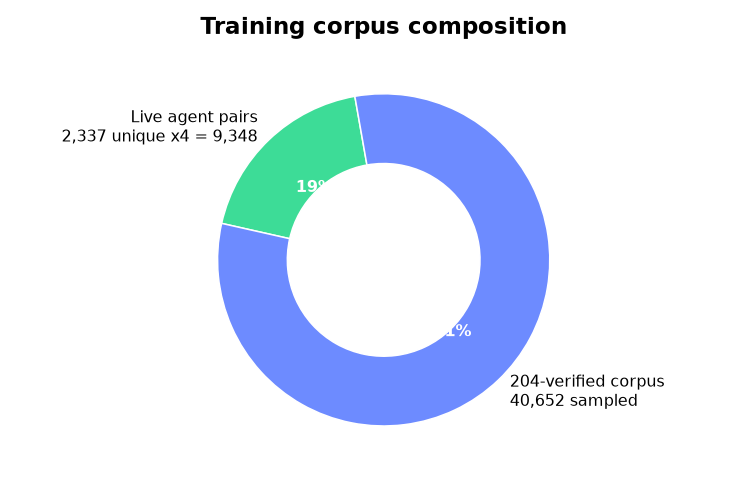
Two data streams are merged into one training corpus: a stratified sample of the 204-verified domain datasets, plus live instruction-response pairs harvested from real production agent sessions.
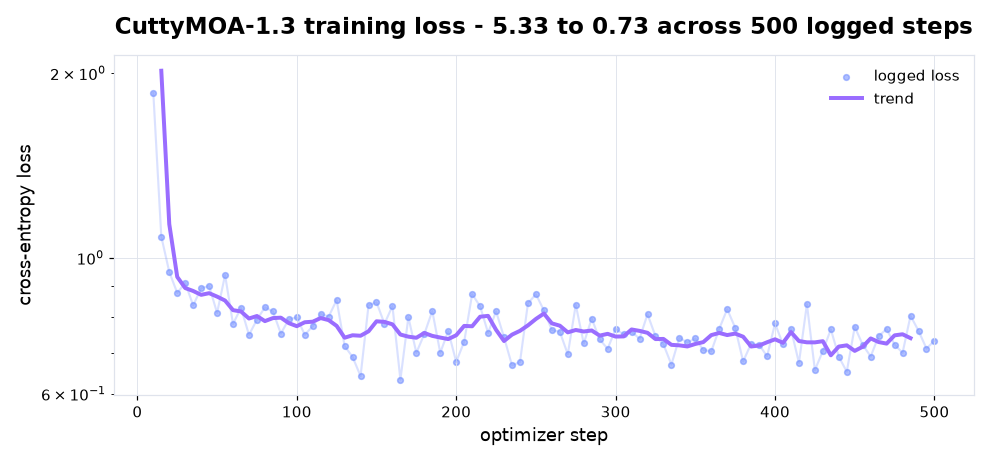
The flagship runs bf16 LoRA training on a 96 GB GPU host: rank-64 adapters across attention, linear-attention and MLP projections, with gradient checkpointing and compiled kernels.
96 GB GPU
Adapters are merged back into the base model, then quantised to GGUF for efficient serving. The same weights ship in three forms: full merged model, GGUF build, and a compact 4B sibling.
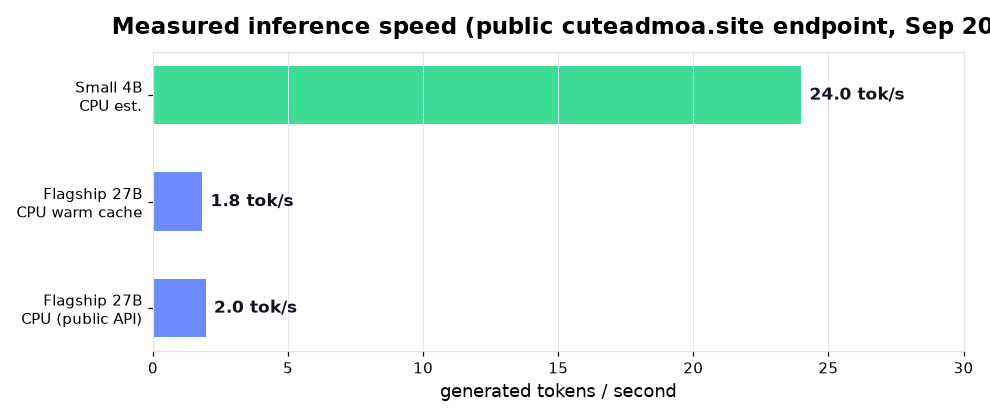
Real logged training metrics and real generation timings — pulled from the actual training run and live endpoint tests.
| Deployment target | tokens / second | Notes |
|---|---|---|
| Public demo — lab CPU, GGUF Q4_K_M | 1.8 – 2.0 | Rate-limited playground endpoint |
| GPU pod — bf16 serving | 25 – 45 | On-demand burst capacity |
| Small 4B — local laptop | 25 – 55 | Estimated for Apple silicon Q4_K_M |
| Flagship 27B on 16 GB laptop | cannot load | Needs ~17 GB even at Q4 |
Point any OpenAI-compatible client at the lab endpoint. Model identifier, limits and a working request below.
https://cuteadmoa.site/v1/v1/chat/completionsCuttyMOA-1.3Bearer <key>Each version is checkpointed and published — nothing is lost between runs.
A 27-billion-parameter model with a native 262,144-token context window. Trained with bf16 LoRA over the full CUTEADMOA corpus, then merged and quantised for serving.
Flagship
The 27B flagship needs at least 17 GB even when heavily quantised, so it cannot run on a 16 GB machine. The Small sibling is trained on the identical corpus and identity, on a compact 4B base — about 2.5 GB at Q4_K_M.
| Generation | Base | Focus | Status |
|---|---|---|---|
| CuttyMOA-1.0 | Dense 8B | First full training pipeline | Published |
| CuttyMOA-1.2 | 35B-A3B MoE | Mixture-of-experts scale-up | Published |
| CuttyMOA-1.3 | Qwen3.8-27B | Flagship — 262K context, hybrid attention | Live |
| CuttyMOA-1.3-Small | Qwen3-4B | Local and edge inference | In pipeline |
The platform ships with a cybersecurity intent layer and an ongoing evaluation loop that keeps the models honest in production.
Concrete, measured steps — not aspirational slideware.
CuttyMOA-1.3-Small plus quantised GGUF packages for llama.cpp and Ollama, so the model runs on ordinary laptops.
Sequence packing and premium GPU hosts to roughly double throughput — enough to see every live agent pair instead of a subset.
A 35B-A3B mixture-of-experts variant: more total parameters while staying fast, because only a fraction activates per token.
Identity retention, scaffolding leakage and per-category spot checks, feeding a repeatable release loop.
A 26-page technical white paper covering the routed model portfolio, the credential fabric, the proxy fleet, governed agent execution and the self-training loop — with a narrated video walkthrough of the same material.
▶
@article{sayeed2026cuteadmoa,
author = {Md Abu Sayeed},
title = {CUTEADMOA: A Unified Mixture-of-Agents Platform with Continuous Self-Training for Autonomous Enterprise AI Automation},
journal = {Advances in Artificial Intelligence and Robotics Research},
volume = {2},
number = {3},
pages = {190--208},
year = {2026},
issn = {3143-3987},
doi = {10.4236/airr.2026.23011},
url = {https://www.scirp.org/journal/paperinformation?paperid=154162}
}
CuttyMOA-1.3 and a bearer key, and use the standard chat completions payload.Bring your data. We shape it, train a model that speaks your domain, and put it behind an API or chat interface you own — no research team required.
A transparent pipeline, run with you at every milestone. You approve each stage before we move on — and you keep ownership of the data and the model.
Your model, your data
We audit your corpus, flag what can't train, and tell you what to fix before a single GPU hour is spent.
Step 01Cleaning, deduplication, structuring and formatting into a dataset that trains reliably.
Step 02LoRA fine-tuning or a full build on your domain, with logged loss and evaluation checkpoints.
Step 03Adapters merged back into the base and packaged in the formats you actually deploy, including GGUF.
Step 04Behind an OpenAI-compatible API or a chat interface you control, with monitoring from day one.
Step 05Quality and identity checks feeding a repeatable update loop, so the model keeps improving.
Step 06Share a few details and we'll come back with a scoped plan and next steps. We only contact people who opt in here.
You get a model tuned to your material, not a generic endpoint you have to re-explain every prompt.
Prefer a quick chat? Add your WhatsApp or Telegram in the form and that's the fastest way to reach you.
Or email us directly at hello@dotaistudio.cloud — every enquiry gets an automatic acknowledgement.
Thanks — your details are in. We'll review your request and reply within 1–2 working days. If you added WhatsApp or Telegram, that's the fastest way to reach you.
Training hardware, serving infrastructure and the tooling around it — the same stack behind the live playground above.


Try the playground in your browser, or wire the OpenAI-compatible endpoint into your own stack.